Why does AI value measurement need evidence beyond speed?
METR’s early-2025 experiment found experienced developers took 19% longer with AI. Its February 2026 update explained why later estimates were affected by selection bias. METR — February 2026 study update.
Evidence limits: The earlier result covered 16 developers and 246 tasks. Neither that result nor the biased follow-up establishes today’s effect for all developers or other occupations.
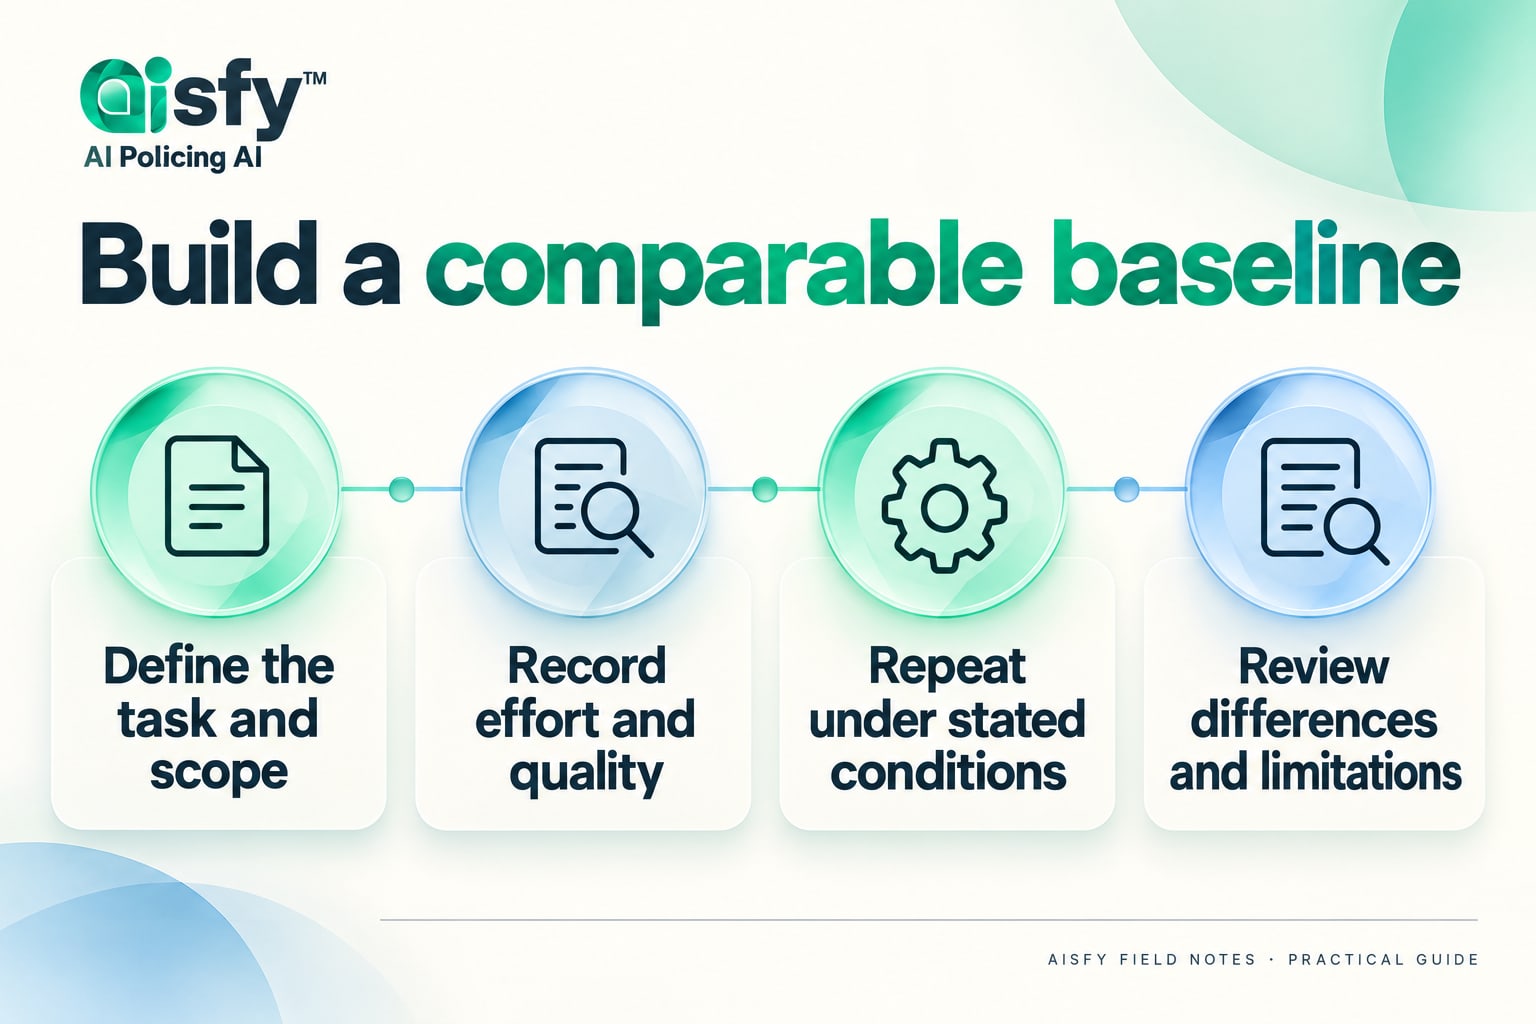
A useful evaluation records when the tool helps and when it adds work. Task selection, prior experience and review standards can change the result. Keep failed attempts in the record so the final comparison does not include only convenient successes.
How can a team calculate cost per accepted AI-assisted output?
Illustrative calculation: a manual task takes 30 minutes, while assisted drafting takes 12 minutes and review takes 10. The apparent saving is eight minutes, not 18. If the assisted output fails the quality threshold, count the retry and review effort before comparing cost per accepted result. This is a calculation example, not an AISFY customer outcome.
Sources checked 20 October 2026. External examples are not AISFY customer results. Practice scenarios are editorial examples.
What did OpenAI propose for measuring AI value?
In its 17 July 2026 scorecard essay, OpenAI argued for assessing useful work relative to its total cost, with attention to reliability and scale. This is a supplier’s commercial perspective, not an independent measurement standard. The practical question for a team is which evidence would justify continuing a particular use case.
Which task belongs in an AI value scorecard?
Choose a bounded output with an identifiable reviewer: an approved service reply, a checked report or a completed internal handover. Define acceptance before collecting results. A draft that still requires substantial checking is not equivalent to a finished work product.
Keep the unit consistent. Comparing a short internal note with a complex customer response can make the assisted method appear faster because the tasks differ. Record task type, source quality, reviewer and difficulty so the comparison can be interpreted.
Which fields make an AI value scorecard auditable?
- Task identifier and date, without unnecessary personal information.
- Method used and the relevant tool or configuration.
- Drafting, review, correction and retry time recorded separately.
- Acceptance result and the reason for rejection or escalation.
- Direct tool cost and the assumptions used to value staff time.
- Known limitations, missing observations and the next review decision.
How should an AI value scorecard handle failed tasks?
Include abandoned attempts and manual fallback. If a team starts ten tasks with assistance but accepts only six outputs, the effort spent on the other four still belongs in the cost record. Report completion and quality alongside speed so that a faster but unreliable process does not appear successful.
Do not assign a cash value to time saved unless the organization has a defensible basis for doing so. Released time may support other work without reducing expenditure. Show that distinction in the report and ask the business owner how the time was actually used.
What does an illustrative AI value calculation reveal?
Consider a fictional batch of ten comparable reports. The manual method takes 20 minutes per report, or 200 minutes in total. With assistance, eight accepted reports take 5 minutes to draft and 10 minutes to check and correct: 120 minutes. Two unsuccessful attempts take 15 minutes each before a 20-minute manual fallback for each report: another 70 minutes.
Total assisted effort is therefore 190 minutes, a 10-minute difference across the batch before setup, training or tool costs. Looking only at drafting would have overstated the benefit. These numbers are an explanation of the method, not an AISFY result or a forecast. A real comparison must also check whether both methods met the same quality threshold.
When should an AI value comparison lead to expansion?
First repeat the comparison on representative work and check whether the result survives different reviewers, source packs and task difficulty. Expansion should have an owner, an agreed quality threshold and a way to stop when errors recur. A small favorable sample is a reason to investigate further, not proof of organization-wide return.
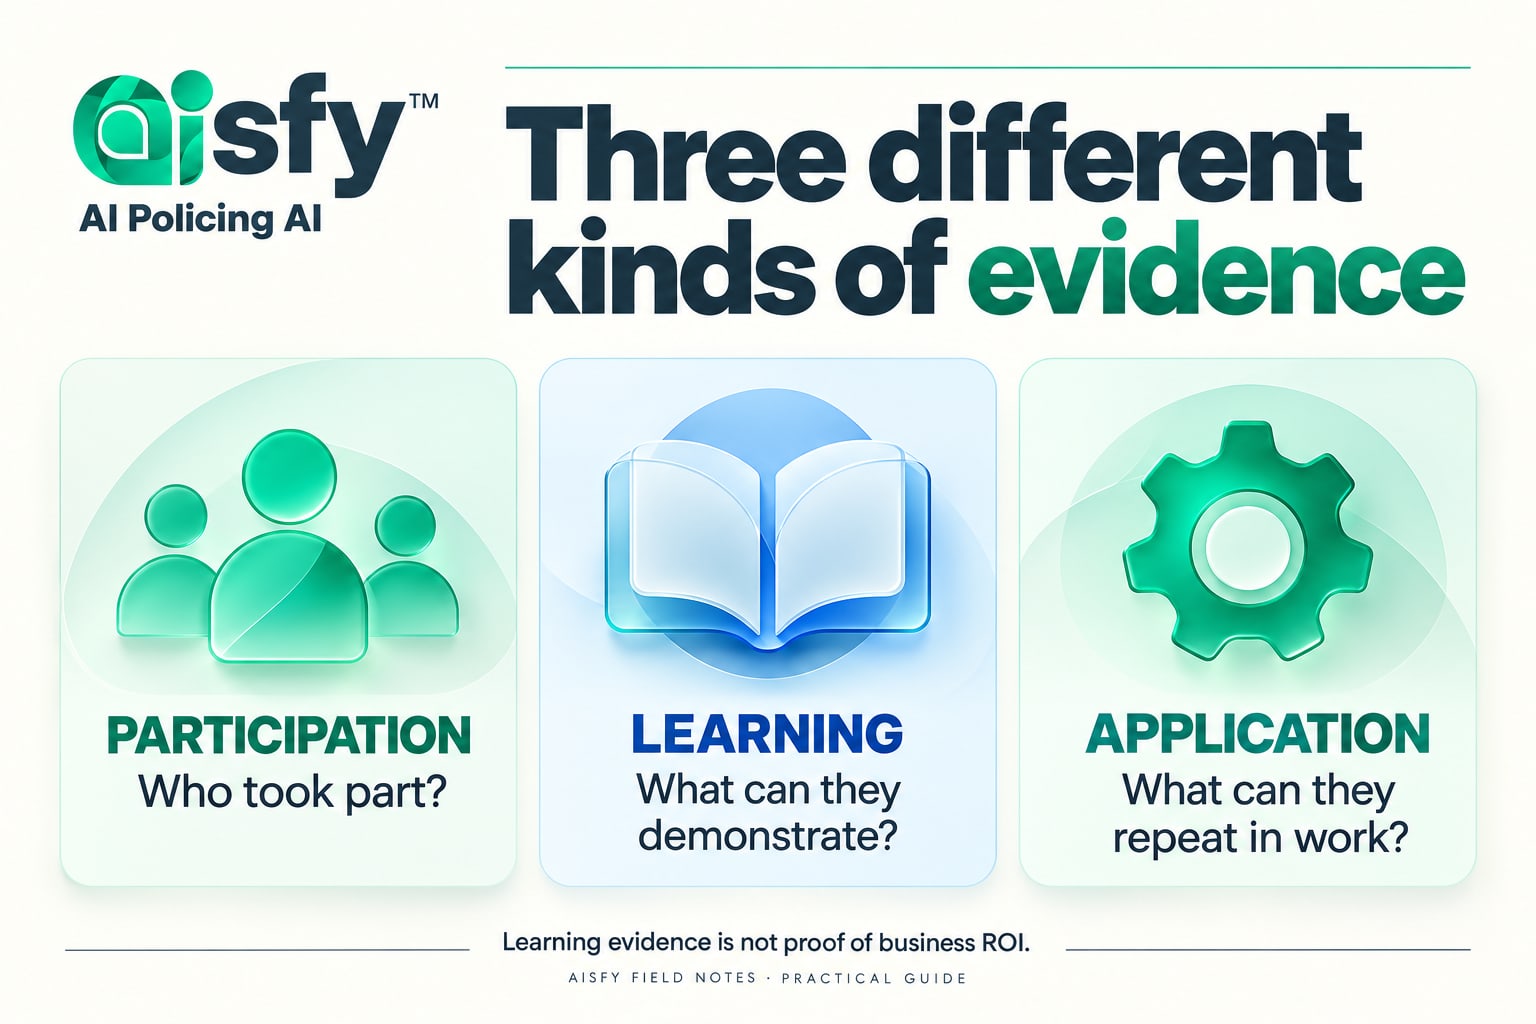
For a practical starting worksheet, use the AI impact measurement baseline. Keep the evidence from employee learning separate from business performance: a successful assessment establishes a demonstrated skill under those conditions, not every later outcome.
What do the visual guides illustrate?